0%

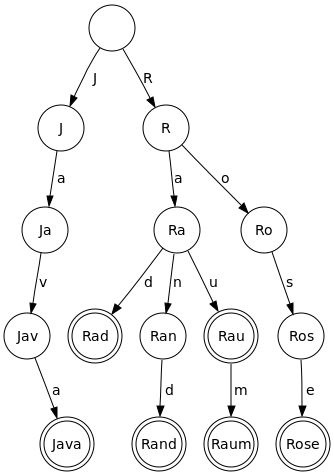
前缀树 又称 字典树, 是一种有序多叉树结构. 常用于做词频统计和前缀匹配. 与二叉树结构不同, 数据不保存在节点中, 而是由路径来表示. 节点中存储标记信息 (当前节点是否为某一单词的结尾、下一可能的字符等). 如下图中所示, 表示了关键字集合 {“Java”, “Rad”, “Rand”, “Rau”, “Raum”, “Rose”}。

例题 1 (LeetCode #208)

实现 Trie (前缀树)

Trie(发音类似 “try”)或者说 前缀树 是一种树形数据结构,用于高效地存储和检索字符串数据集中的键。这一数据结构有相当多的应用情景,例如自动补完和拼写检查。

请你实现 Trie 类:

  • Trie() 初始化前缀树对象。
  • void insert(String word) 向前缀树中插入字符串 word 。
  • boolean search(String word) 如果字符串 word 在前缀树中,返回 true(即,在检索之前已经插入);否则,返回 false 。
  • boolean startsWith(String prefix) 如果之前已经插入的字符串 word 的前缀之一为 prefix ,返回 true ;否则,返回 false 。

示例:

输入
[“Trie”, “insert”, “search”, “search”, “startsWith”, “insert”, “search”]
[[], [“apple”], [“apple”], [“app”], [“app”], [“app”], [“app”]]
输出
[null, null, true, false, true, null, true]

解释

1
2
3
4
5
6
7
Trie trie = new Trie();
trie.insert("apple");
trie.search("apple"); // 返回 True
trie.search("app"); // 返回 False
trie.startsWith("app"); // 返回 True
trie.insert("app");
trie.search("app"); // 返回 True

提示:

  • 1 <= word.length, prefix.length <= 2000
  • word 和 prefix 仅由小写英文字母组成
  • insert、search 和 startsWith 调用次数 总计 不超过 3 * 104 次

题解

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
class TrieNode {
boolean isEnd; // 记录当前节点是否为某一单词的最后一个字母
TrieNode[] children = new TrieNode[26]; // 同时记录下一个字母(索引)及其对应的节点对象
}

class Trie {
private final TrieNode root;

public Trie() {
this.root = new TrieNode();
}

public void insert(String word) {
TrieNode cur = root;
for (char c : word.toCharArray()) {
int nextIdx = c - 'a';
if (cur.children[nextIdx] == null) {
cur.children[nextIdx] = new TrieNode();
}
cur = cur.children[nextIdx];
}
cur.isEnd = true;
}

public boolean search(String word) {
TrieNode cur = root;
for (char c : word.toCharArray()) {
int nextIdx = c - 'a';
if (cur.children[nextIdx] == null) return false;
cur = cur.children[nextIdx];
}
return cur.isEnd;
}

public boolean startsWith(String prefix) {
TrieNode cur = root;
for (char c : prefix.toCharArray()) {
int nextIdx = c - 'a';
if (cur.children[nextIdx] == null) return false;
cur = cur.children[nextIdx];
}
return true;
}
}

例题 2 (LeetCode #212)

单词搜索 II

给定一个 m x n 二维字符网格 board 和一个单词(字符串)列表 words, 返回所有二维网格上的单词 。

单词必须按照字母顺序,通过 相邻的单元格 内的字母构成,其中“相邻”单元格是那些水平相邻或垂直相邻的单元格。同一个单元格内的字母在一个单词中不允许被重复使用。

示例 1:

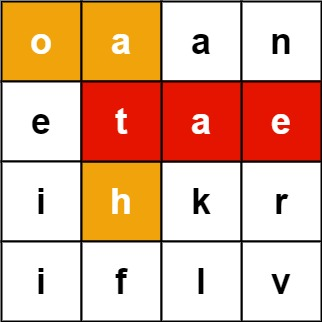
输入:board = [[“o”,”a”,”a”,”n”],[“e”,”t”,”a”,”e”],[“i”,”h”,”k”,”r”],[“i”,”f”,”l”,”v”]], words = [“oath”,”pea”,”eat”,”rain”]
输出:[“eat”,”oath”]

示例 2:

输入:board = [[“a”,”b”],[“c”,”d”]], words = [“abcb”]
输出:[]

提示:

  • m == board.length
  • n == board[i].length
  • 1 <= m, n <= 12
  • board[i][j] 是一个小写英文字母
  • 1 <= words.length <= 3 * 104
  • 1 <= words[i].length <= 10
  • words[i] 由小写英文字母组成
  • words 中的所有字符串互不相同

题解

可使用前缀树优化 words 中单词的搜索过程,以下解法中前缀树节点直接保存了以当前字母为结尾的单词,以省去添加符合条件的字符串时的二次遍历。

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
class TrieNode {

String s;
TrieNode[] children = new TrieNode[26];

public void insert(String s, TrieNode cur) {
for (char c : s.toCharArray()) {
int nextIdx = c - 'a';
if (cur.children[nextIdx] == null) {
cur.children[nextIdx] = new TrieNode();
}
cur = cur.children[nextIdx];
}
cur.s = s;
}

}

class Solution {

private Set<String> result;
private char[][] board;
private boolean[][] visited;
private int m, n;
private int[][] directions = {{0, -1}, {0, 1}, {1, 0}, {-1, 0}};

public List<String> findWords(char[][] board, String[] words) {
m = board.length;
n = board[0].length;

result = new HashSet<>();
this.board = board;
visited = new boolean[m][n];

TrieNode root = new TrieNode();
for (String word : words) root.insert(word, root);

for (int i = 0; i < m; i++) {
for (int j = 0; j < n; j++) {
int cur = board[i][j] - 'a';
if (root.children[cur] != null) dfs(i, j, root.children[cur]);
}
}

return new ArrayList<>(result);
}

private void dfs(int i, int j, TrieNode node) {
if (node.s != null && node.s.length() > 10) return;

if (node.s != null) result.add(node.s);

visited[i][j] = true;
for (int[] direction : directions) {
int newI = i + direction[0], newJ = j + direction[1];
if (newI < 0 || newI >= m || newJ < 0 || newJ >= n || visited[newI][newJ]) continue;
int nextIdx = board[newI][newJ] - 'a';
if (node.children[nextIdx] != null) {
dfs(newI, newJ, node.children[nextIdx]);
}
}
visited[i][j] = false;
}
}

并查集是一种树型的数据结构,用于处理一些不交集(Disjoint Sets)的合并及查询问题。有一个联合-查找算法(union-find algorithm)定义了两个用于此数据结构的操作:

  • Union:将两个子集合并成同一个集合
  • isSameSet:判断两元素是否属于同一集合

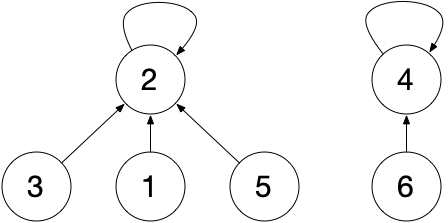
并查集中的元素类似单链表中的结点, 其指针指向该节点的父结点, 集合的代表结点的指针指向它本身.

在合并两个两个集合的过程中, 一般将小的集合挂载大集合的代表结点之后. 如下图中的两个集合合并, 4 将挂在 2 下, 新集合的代表结点即为 2.

在查询 (执行 isSameSet 方法) 的过程中, 只需判断两结点所在集合的代表结点是否相同即可判断是否为同一集合.

查询或合并集合时, 若集合未经整理, 即包含多层结点 ( 如3->1->5->2 ), 需整理为如图中的仅有两层的形式, 以减少下次查询的操作数.

实现

Java

使用 HashMap 来表示结点之间的关系, (key, value) 即表示 key 的父节点是 value. 用另一个 HashMap 来存各储代表结点和集合大小, 若某结点不是代表结点, 则该节点的 size 信息无效.

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
class Data {
// 自定义数据类型
}

public class UnionFindSet {
public HashMap<Data, Data> parentMap;
public HashMap<Data, Integer> sizeMap;

public UnionFindSet(List<Data> nodes) {
parentMap = new HashMap<>();
sizeMap = new HashMap<>();

// 初始化并查集, 此时每个结点自成一个集合, 指针指向它本身
for (Data node : nodes) {
parentMap.put(node, node);
sizeMap.put(node, 1);
}
}

/**
* 找到代表结点并整理结点
*
* @param node 当前节点
* @return 代表结点
*/
private Data findHead(Data node) {
Data parent = parentMap.get(node);
if (parent != node) {
parent = findHead(parent);
}

parentMap.put(node, parent); // 整理结点
return parent;
}

public boolean isSameSet(Data node1, Data node2) {
return findHead(node1) == findHead(node2);
}

public void union(Data a, Data b) {
if (a == null || b == null)
return;
Data aHead = findHead(a);
Data bHead = findHead(b);

if (aHead == bHead)
return;

int aSetSize = sizeMap.get(aHead);
int bSetSize = sizeMap.get(bHead);

if (aSetSize <= bSetSize) {
parentMap.put(bHead, aHead);
sizeMap.put(bHead, aSetSize + bSetSize);
} else {
parentMap.put(aHead, bHead);
sizeMap.put(aHead, aSetSize + bSetSize);
}
}
}
Python
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
class Data:
pass

class UnionFindSet:
parent_dict = dict()
size_dict = dict()

def __init__(self, nodes):
for node in nodes:
self.parent_dict[node] = node
self.size_dict[node] = 1

def find_head(self, node):
parent = self.parent_dict.get(node)
if parent != node:
self.find_head(parent)

self.parent_dict[node] = parent
return parent

def is_same_set(self, node1, node2):
return self.find_head(node1) == self.find_head(node2)

def union(self, node1, node2):
if node1 and node2:
head1 = self.find_head(node1)
head2 = self.find_head(node2)

if head1 == head2:
return

size1 = self.size_dict.get(head1)
size2 = self.size_dict.get(head2)

if size1 <= size2:
self.parent_dict[head1] = head2
self.size_dict[head2] = size1 + size2
else:
self.parent_dict[head2] = head1
self.size_dict[head1] = size1 + size2

时间复杂度

当查询次数和合并次数达到 O(N) 或以上时, 单次查询和单次合并的时间复杂度平均为 O(1)

寻找峰值元素 (LeetCode #162)

给定一个输入数组 nums ,其中 nums[i] ≠ nums[i+1] ,找到峰值元素并返回其索引。

数组可能包含多个峰值,在这种情况下,返回任何一个峰值所在位置即可。

你可以假设 nums[-1] = nums[n] = -∞ 。

示例 1:

输入: nums = [1,2,3,1]
输出: 2
解释: 3 是峰值元素,你的函数应该返回其索引 2。

示例 2:

输入: nums = [1,2,1,3,5,6,4]
输出: 1 或 5
解释: 你的函数可以返回索引 1,其峰值元素为 2;
或者返回索引 5, 其峰值元素为 6。

说明:

解法应该是 O(logN) 时间复杂度的.

题解

本题采用二分法, 假定最后一个元素的索引为 N, 首先判断 0 和 1 位置元素, N 和 N-1 位置元素的大小关系, 若 num[0] > num[1] 或 num[N] > num[N-1] , 则返回 0 或 N 即可. 若前两个条件均不满足则 0 和 N 之间必有峰值, 取中间元素 num[mid] , 若该元素也不是峰值, 则继续二分. 若 num[mid] < num[mid-1] , 则峰值必在 0 和 mid 之间, 反之则在 mid 与 N 之间.

Java
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
public class FindPeakElement {
public static int findPeakElement(int[] nums) {
int left = 0;
int right = nums.length - 1;
int mid = 0;

while (left < right) {
mid = left + (right - left) / 2;
if (nums[mid] > nums[mid + 1]) right = mid; // 左边高, 峰值在左, 可能是 mid
else left = mid + 1; // 右边高, 峰值在右, 包含 mid + 1
}

return left;
}
}
Python
1
2
3
4
5
6
7
8
9
10
11
12
class FindPeakElement:
def findPeakElement(self, nums):
left = 0
right = len(nums) - 1
mid = 0

while (left < right):
mid = left + (right - left) // 2
if nums[mid] > nums[mid + 1]: right = mid
else: left = mid + 1

return left

题目

给定一棵二叉树和其中的一个结点, 求该结点的中序遍历后继, 结点定义如下:

1
2
3
4
5
6
7
8
9
10
class Node {
int val;
Node left;
Node right;
Node parent;

public Node(int val) {
this.val = val;
}
}

题解

结点的中序后继有以下几种情况:

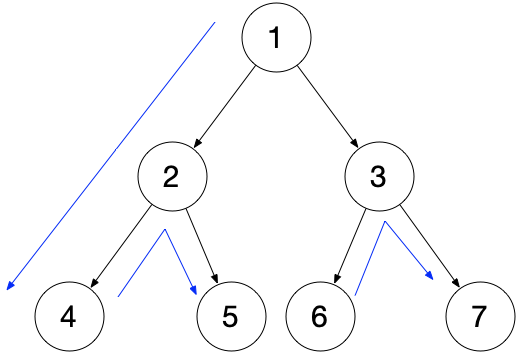
  • 结点有右子树: 该节点的中序后继即为其右子树最左的结点, 如头图中 1 的后继即为 6
  • 结点没有右子树: 则需一直向上查找, 直到某个结点为其父结点的左子树为止, 其后继即为该父节点, 如 5 的后继为 1; 若无满足条件的结点则返回 null, 如 7 无后继
Java
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
public class FindSuccessor {
public static Node findSuccessor(Node node) {
if (node == null)
return null;

if (node.right != null) {
return getLeftMost(node.right);
} else {
Node parent = node.parent;
while (parent != null && parent.left != node) {
node = parent;
parent = node.parent;
}
return parent;
}
}

public static Node getLeftMost(Node node) {
if (node != null){
while (node.left != null) {
node = node.left;
}
}

return node;
}
}
Python
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
class Node:
def __init__(self, val):
self.val = val
self.left = None
self.right = None
self.parent = None


class FindSuccessor:
def get_successor(self, node):
if not node:
return None

if node.right:
return self.get_left_most(node.right)
else:
parent = node.parent
while parent and parent.left != node:
node = parent
parent = node.parent

return parent

def get_left_most(self, node):
if node:
while node.left:
node = node.left
return node

题目 (牛客网)

请把纸条竖着放在桌⼦上,然后从纸条的下边向上⽅对折,压出折痕后再展 开。此时有1条折痕,突起的⽅向指向纸条的背⾯,这条折痕叫做“下”折痕 ;突起的⽅向指向纸条正⾯的折痕叫做“上”折痕。如果每次都从下边向上⽅ 对折,对折N次。请从上到下计算出所有折痕的⽅向。

给定折的次数n,请返回从上到下的折痕的数组,若为下折痕则对应元素为”down”,若为上折痕则为”up”.

测试样例:

1
1
1
返回: ["down"]

题解

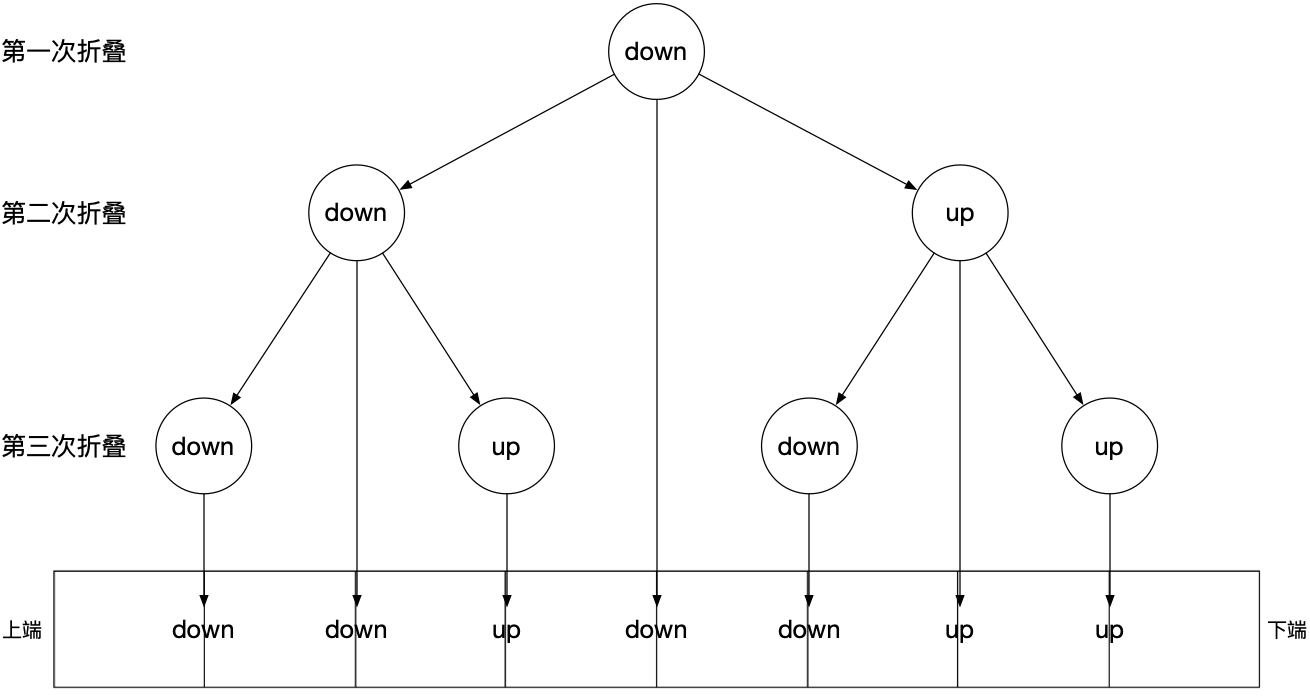
该题可看作一棵二叉树, 树的头结点为 down, 所有左子树的头结点都为 down, 所有右子树的头结点都为 up, 最终从上到下的折痕顺序为该二叉树的中序遍历结果.

因左右子树的头结点分别为 down 或 up, 故可用 down 的布尔值代替左右, 省去创建节点的空间. 以下实现最大空间复杂度为树的高度, 即折叠次数.

Java
1
2
3
4
5
6
7
8
9
10
11
12
13
14
public class FoldPaper {
public static void printAllFolds(int N) {
printProcess(1, N, true);
}

public static void printProcess(int i, int N, boolean down) {
if (i > N)
return;

printProcess(i + 1, N, true);
System.out.print(down ? "down " : "up ");
printProcess(i + 1, N, false);
}
}
Python
1
2
3
4
5
6
7
8
9
10
11
12
13
def print_all_folds(N):
print_process(1, N, True)


def print_process(i, N, down):
if i > N: return

print_process(i + 1, N, True)
print("down", end=" ") if down else print("up", end=" ")
print_process(i + 1, N, False)


print_all_folds(4)

题目 (LeetCode #94, #144, #145)

先序遍历

利用栈实现二叉树的非递归遍历, 先将头结点放入栈中, 若栈不为空则一直循环, 弹出栈中元素, 若弹出的元素含有子节点则将子元素按先右后左的顺序压入栈中, 直到所有节点全部弹出.

Java
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
class TreeNode {
int val;
TreeNode left;
TreeNode right;

public TreeNode(int val) {
this.val = val;
}
}

public class PreorderTraversal {
public List<Integer> preorderTraversal(TreeNode root) {
List<Integer> result = new ArrayList<>();

if (root != null) {
Stack<TreeNode> stack = new Stack<>();
stack.push(root);

TreeNode tmp;
while (!stack.isEmpty()) {
tmp = stack.pop();
result.add(tmp.val);

if (tmp.right != null) {
stack.push(tmp.right);
}

if (tmp.left != null) {
stack.push(tmp.left);
}
}
}

return result;
}
}
Python
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
class PreorderTraversal:
def preorder_traversal(self, root):
result = []

if root:
stack = []
stack.append(root)

while stack:
tmp = stack.pop()
result.append(tmp.val)

if tmp.right: stack.append(tmp.right)
if tmp.left: stack.append(tmp.left)

return result

后序遍历

后序遍历可仿照先序遍历, 改变左右子树入栈顺序, 即先入栈左子树, 后入栈右子树, 以实现中右左依次出栈. 出栈时, 先将出栈元素放入另一个辅助栈中, 再全部依次出栈, 这样即实现了对每棵子树的逆序, 即最终为左右中的后序遍历顺序.

Java
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
public class PostorderTraversal {
public static List<Integer> postorderTraversal(TreeNode root) {
List<Integer> result = new ArrayList<>();

if (root != null) {
Stack<TreeNode> stack = new Stack<>();
Stack<TreeNode> help = new Stack<>();
stack.add(root);

TreeNode tmp;
while (!stack.isEmpty()) {
tmp = stack.pop();
help.push(tmp);

if (tmp.left != null) {
stack.push(tmp.left);
}

if (tmp.right != null) {
stack.push(tmp.right);
}
}

while (!help.isEmpty()) {
result.add(help.pop().val);
}
}

return result;
}
}
Python
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
class PostorderTraversal:
def postorder_traversal(self, root):
result = []

if root:
stack = []
help_stack = []
stack.append(root)

while stack:
tmp = stack.pop()
help_stack.append(tmp.val)

if tmp.left: stack.append(tmp.left)
if tmp.right: stack.append(tmp.right)

while help_stack:
result.append(help_stack.pop())

return result

中序遍历

先将左边界全部压入栈中, 再逐级向上弹出, 弹出过程中若该节点的左子树不为 null 则压入该左子树的边界.

Java
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
public class InorderTraversal {
public List<Integer> inorderTraversal(TreeNode root) {
List<Integer> result = new ArrayList<>();
if (root != null) {
Stack<TreeNode> stack = new Stack<>();
while (!stack.isEmpty() || root != null) {
if (root != null) {
stack.push(root);
root = root.left;
} else {
root = stack.pop();
result.add(root.val);
root = root.right;
}
}
}

return result;
}
}
Python
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
class InorderTraversal:
def inorder_traversal(self, root):
result = []

if root:
stack = []

while stack or root:
if root:
stack.append(root)
root = root.left
else:
root = stack.pop()
result.append(root.val)
root = root.right

return result

题目 (LeetCode #502)

假设 力扣(LeetCode)即将开始其 IPO。为了以更高的价格将股票卖给风险投资公司,力扣 希望在 IPO 之前开展一些项目以增加其资本。 由于资源有限,它只能在 IPO 之前完成最多 k 个不同的项目。帮助 力扣 设计完成最多 k 个不同项目后得到最大总资本的方式。

给定若干个项目。对于每个项目 i,它都有一个纯利润 Pi,并且需要最小的资本 Ci 来启动相应的项目。最初,你有 W 资本。当你完成一个项目时,你将获得纯利润,且利润将被添加到你的总资本中。

总而言之,从给定项目中选择最多 k 个不同项目的列表,以最大化最终资本,并输出最终可获得的最多资本。

示例 1:

输入: k=2, W=0, Profits=[1,2,3], Capital=[0,1,1].

输出: 4

解释:
由于你的初始资本为 0,你尽可以从 0 号项目开始。
在完成后,你将获得 1 的利润,你的总资本将变为 1。
此时你可以选择开始 1 号或 2 号项目。
由于你最多可以选择两个项目,所以你需要完成 2 号项目以获得最大的资本。
因此,输出最后最大化的资本,为 0 + 1 + 3 = 4。

注意:

  1. 假设所有输入数字都是非负整数。
  2. 表示利润和资本的数组的长度不超过 50000。
  3. 答案保证在 32 位有符号整数范围内。

题解

本题是一个标准的贪心问题, 每一轮投资可以分为两步, 先将所有项目按成本 C 排序放入一个小根堆中, 再将所有成本小于现有资本的项目弹出, 按纯利润 P 排序放入另一个大根堆中, 弹出利润最高的元素, 将利润 P 与原资本相加得到新的资本, 循环以上步骤, 直至做完 k 个项目.

Java
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
public class MaximizedCapital {
static class Node {
public int p;
public int c;

public Node(int p, int c) {
this.p = p;
this.c = c;
}
}

public static int findMaximizedCapital(int k, int W, int[] Profits, int[] Capital) {
PriorityQueue<Node> minCost = new PriorityQueue<>((a, b) -> {
return a.c - b.c;
});
PriorityQueue<Node> maxProfit = new PriorityQueue<>((a, b) -> {
return b.p - a.p;
});

for (int i = 0; i < Profits.length; i++) {
minCost.add(new Node(Profits[i], Capital[i]));
}

for (int i = 0; i < k; i++) {
while (!minCost.isEmpty() && minCost.peek().c <= W){
maxProfit.add(minCost.poll());
}

if (maxProfit.isEmpty()){
return W;
}

W += maxProfit.poll().p;
}
return W;
}
}
Python

计算利润时, 成本不影响结果, 故可只取利润存入列表中.

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
class MaximizedCapital:
def findMaximizedCapital(self, k, W, Profits, Capital):
captal = sorted(list(zip(Capital, Profits)), key=lambda x: -x[0])
profit = []

for i in range(k):
while captal and captal[-1][0] <= W:
profit.append(captal.pop()[1])

tmp_max = max(profit) if profit else 0
W += tmp_max
if profit:
profit.remove(tmp_max)
return W

题目

一块金条切成两半, 是需要花费和长度数值一样的铜板的. 比如长度为 20 的 金条, 不管切成长度多大的两半, 都要花费 20 个铜板. 一群人想整分整块金条, 怎么分最省铜板?

例, 给定数组 {10,20,30}, 代表一共三个人, 整块金条长度为 10 + 20 + 30 = 60 . 金条要分成 10, 20, 30 三个部分.

  • 如果先把长度 60 的金条分成 10 和 50 , 花费 60 再把长度 50 的金条分成 20 和 30, 花费 50 , 一共花费 110 铜板.
  • 如果先把长度 60 的金条分成 30 和 30, 花费 60 再把长度 30 金条分成 10 和 20 ,花费 30 一共花费 90 铜板.

输入一个数组, 返回分割的最小代价.

题解

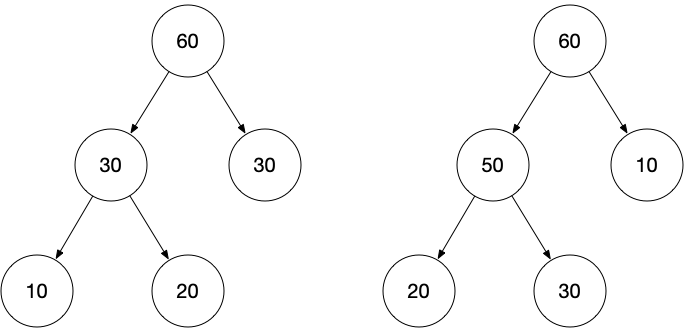
如图, 该问题可看作哈夫曼树, 树中的叶结点即为最终的划分结果, 相当于给了叶结点, 求什么情况下非叶结点的和最小. 可采用贪心算法, 利用堆结构. 将所有节点存入小根堆中. 每次依次弹出两个元素, 求和, 并将和放回小根堆中, 循环计算即可得到最小值.

Java
1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
import java.util.PriorityQueue;

public class MinimalCost {
PriorityQueue<Integer> priorityQueue = new PriorityQueue<>();

public int getMinimalCost() {
while (priorityQueue.size() != 1) {
int tmp1 = priorityQueue.poll();
int tmp2 = priorityQueue.poll();
priorityQueue.add(tmp1 + tmp2);
}

return priorityQueue.peek();
}
}
Python
1
2
3
4
5
6
7
8
9
10
11
from heapq import *

def get_minimal_cost(result_list):
heapify(result_list)

while len(result_list) != 1:
tmp1 = heappop(result_list)
tmp2 = heappop(result_list)
heappush(result_list, tmp1 + tmp2)

return result_list[0]

题目 (LeetCode #189)

有一个源源不断地生成整数的数据流, 假设你有足够的空间来保存生成的数. 设计一个名叫 MedianHolder 的结构, 使之可以随时取得之前生成的所有数的中位数.

要求

  1. 如果 MedianHolder 已经保存了生成的 N 个数, 那么任意时刻将一个新数加入到 MedianHolder 的过程, 其时间复杂度是 O(logN)
  2. 取得已经产生的 N 个数整体的中位数的过程, 时间复杂度为 O(1)

题解

创建一个大根堆和一个小根堆, 尽量保证两个堆中元素数量均为 n/2 , 在添加元素时, 新元素若大于大根堆堆顶元素则放入小根堆, 若小于小根堆堆顶则放入大根堆, 这样即可保证前 n/2 个数都在大根堆中, 后 n/2 个数都在小根堆中, 中位数即为两堆的堆顶元素. 添加元素的同时确保小根堆的长度不小于大根堆, 若最后数据总数为奇数, 中位数即为小根堆堆顶元素; 若为偶数则为两堆堆顶元素和的一半.

添加新数的时间复杂度即为堆调整的时间复杂度, 即 O(logN) , 取得中位数的时间复杂度为 O(1)

Java

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
class MedianHolder {
private PriorityQueue<Integer> maxHeap = new PriorityQueue<>((a, b) -> b - a);
private PriorityQueue<Integer> minHeap = new PriorityQueue<>();

public void addNum(int num) {
minHeap.add(num);
maxHeap.add(minHeap.poll());
if (minHeap.size() < maxHeap.size())
minHeap.add(maxHeap.poll());
}

public double getMedian() {
if (maxHeap.size() == minHeap.size()) {
return (maxHeap.peek() + minHeap.peek()) / 2.0;
} else {
return minHeap.peek();
}
}
}

Python

heapq 中默认定义为小根堆, 通过保存相反数实现大根堆.

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
from heapq import *
class MedianFinder:
def __init__(self):
self.max_heap = []
self.min_heap = []

def addNum(self, num):
heappush(self.min_heap, num)
heappush(self.max_heap, -heappop(self.min_heap))
if len(self.min_heap) < len(self.max_heap):
heappush(self.min_heap, -heappop(self.max_heap))

def findMedian(self):
max_len = len(self.max_heap)
min_len = len(self.min_heap)

if min_len == 0:
return

return self.min_heap[0] if max_len != min_len else (-self.max_heap[0] + self.min_heap[0]) / 2.0

题目

给定两个单链表的头结点 head1 和 head2 , 这两个链表可能有环也可能无环, 请判断这两个链表是否相交, 若相交则返回第一个相交结点

要求

如果链表的长度分别为 M 和 N , 时间复杂度为 O(M+N) , 额外空间复杂度为 O(1)

题解

可采用先将一个链表中的结点放入 HashSet 中, 再遍历另一个链表判断结点是否已在该 HashSet 中的方法, 但额外空间复杂度不符合条件.

不使用 HashSet 的解法:

先判断链表是否有环

  1. 若链表无环

    此时若两链表相交则至少共用两链表的最后一个结点, 只需判断两链表的最后一个结点是否相同即可. 若要找到第一个相交结点需先统计链表长度 L1 和 L2 , 较长的链表的指针先移动 abs(L1-L2) 步, 剩余的部分即与较短的链表长度相同, 再同时移动相同步数后即可找到第一个相交结点.

  2. 若一个链表有环一个无环

    此时对两个单链表来说二者不可能相交

  3. 若两个链表都有环

    此时有三种情况

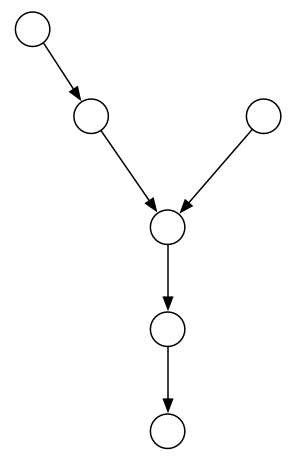
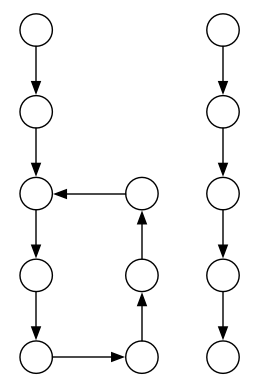
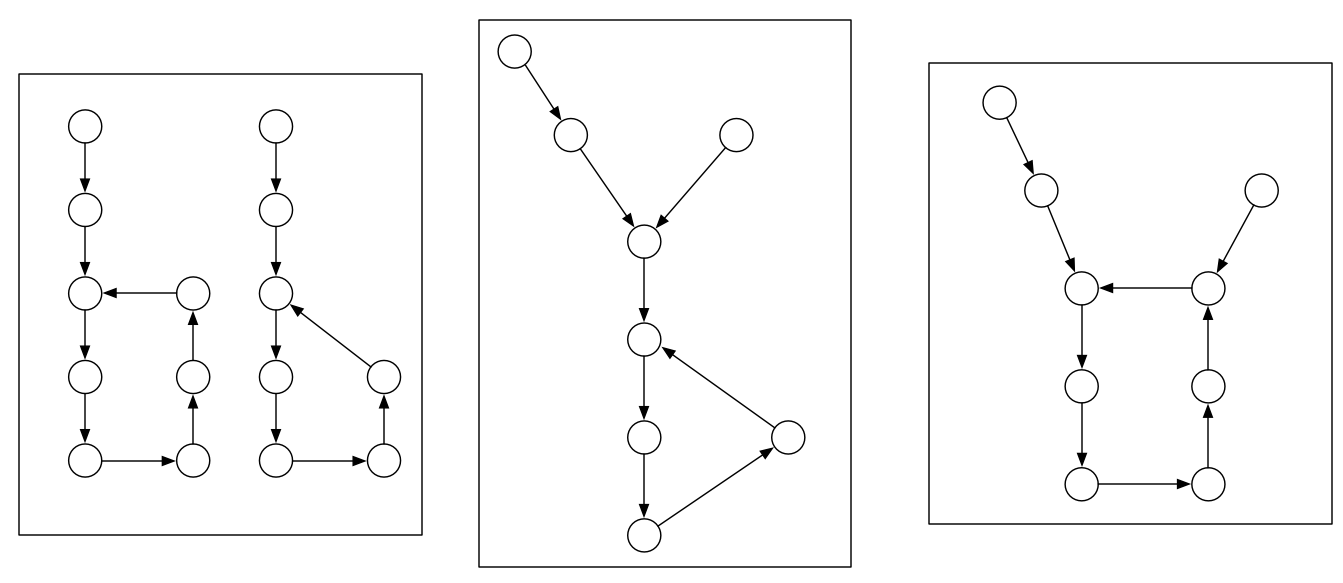
    • 若两个链表的入环结点相同, 则为图2
    • 若另两个链表的入环结点不同, 则可能有图 1 和图 3 两种可能. 可从一个入环结点开始继续遍历, 若再次遍历回该结点之前经过了另一个入环结点则为图 3 情况, 否则为图 1 情况, 即二者不相交.

Java

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
80
81
82
83
84
85
86
87
88
89
90
91
92
93
94
95
96
97
98
99
100
101
102
103
104
105
106
107
108
109
110
111
112
113
114
115
116
117
118
119
120
121
122
123
124
125
126
127
class ListNode {
int val;
ListNode next;

ListNode(int x) {
val = x;
}
}

public class IntersectionList {
public static ListNode getEntrance(ListNode head) {
if (head == null || head.next == null || head.next.next == null)
return null;

ListNode slow = head.next;
ListNode fast = head.next.next;

while (slow != fast) {
if (fast.next == null || fast.next.next == null)
return null;
slow = slow.next;
fast = fast.next.next;
}

fast = head;

while (fast != slow) {
slow = slow.next;
fast = fast.next;
}

return slow;
}

/**
* 当 entranceA 和 entranceB 设为 null 时, 为求两个无环链表的交点,
* 当 entranceA 和 entranceB 不为 null 时, 为求交点在入环结点前的两个链表的交点
*
* @param headA 链表 1 的头结点
* @param entranceA 链表 1 的入环结点, 若无环则为 null
* @param headB 链表 2 的头结点
* @param entranceB 链表 2 的入环结点, 若无环则为 null
* @return 两链表的交点
*/
public ListNode getNodeHelper1(ListNode headA, ListNode entranceA, ListNode headB, ListNode entranceB) {
ListNode tmpA = headA;
ListNode tmpB = headB;
int count = 0;

while (tmpA != entranceA) {
count++;
tmpA = tmpA.next;
}

while (tmpB != entranceB) {
count--;
tmpB = tmpB.next;
}

if (tmpA != tmpB)
return null;

// 无论 A 和 B 谁长都能保证 tmpA 始终指向长的, tmpB 指向短的
tmpA = count > 0 ? headA : headB;
tmpB = tmpA == headA ? headB : headA;
count = count > 0 ? count : -count;

// 将长的链表指针拨到与另一条链表等长处
while (count != 0) {
count--;
tmpA = tmpA.next;
}

while (tmpA != tmpB) {
tmpA = tmpA.next;
tmpB = tmpB.next;
}

return tmpA;
}

/**
* 当两链表均有环且入环结点不同, 即两链表交点在环上时
*
* @param entranceA 链表 1 入环结点
* @param entranceB 链表 2 入环结点
* @return 两链表交点
*/
public ListNode getNodeHelper2(ListNode entranceA, ListNode entranceB) {
ListNode tmpA = entranceA.next;

while (tmpA != entranceA) {
if (tmpA == entranceB)
return tmpA;
tmpA = tmpA.next;
}

return null;
}

public ListNode getIntersectionNode(ListNode headA, ListNode headB) {
if (headA == null || headB == null)
return null;

ListNode entranceA = getEntrance(headA);
ListNode entranceB = getEntrance(headB);

// 两链表均无环
if (entranceA == null && entranceB == null) {
return getNodeHelper1(headA, null, headB, null);
}

// 两链表均有环
if (entranceA != null && entranceB != null) {
// 两链表入环结点相同, 交点在入环结点前或与入环结点重合
if (entranceA == entranceB) {
return getNodeHelper1(headA, entranceA, headB, entranceB);
}

// 两链表交点在环上(此时两个入环结点均可为交点, 情况 3), 或两个带环链表无交点(情况 1)
return getNodeHelper2(entranceA, entranceB);
}

// 一个链表有环, 一个链表无环, 不可能相交, 直接返回
return null;
}
}

Python

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
48
49
50
51
52
53
54
55
56
57
58
59
60
61
62
63
64
65
66
67
68
69
70
71
72
73
74
75
76
77
78
79
class ListNode:
def __init__(self, x):
self.val = x
self.next = None


class IntersectionList:
def get_entrance(self, head):
if head and head.next and head.next.next:
slow = head.next
fast = head.next.next

while slow != fast:
if fast.next and fast.next.next:
slow = slow.next
fast = fast.next.next
else:
return None

fast = head
while slow != fast:
slow = slow.next
fast = fast.next

return fast
else:
return None

def get_length(self, head, entrance):
count = 0
while head and head != entrance:
count += 1
head = head.next

return count, head

def get_node_helper1(self, head_a, head_b, entrance_a=None, entrance_b=None):
length_a, tail_a = self.get_length(head_a, entrance_a)
length_b, tail_b = self.get_length(head_b, entrance_b)

tmp_a = head_a if length_a > length_b else head_b
tmp_b = head_b if tmp_a == head_a else head_a
steps = abs(length_a - length_b)

while steps != 0:
steps -= 1
tmp_a = tmp_a.next

while tmp_a != tmp_b:
tmp_a = tmp_a.next
tmp_b = tmp_b.next

return tmp_a

def get_node_helper2(self, entrance_a, entrace_b):
tmp_a = entrance_a.next

while tmp_a != entrance_a:
if tmp_a == entrace_b:
return tmp_a
tmp_a = tmp_a.next

return None

def get_intersection_node(self, head_a, head_b):
if head_a and head_b:
entrance_a = self.get_entrance(head_a)
entrance_b = self.get_entrance(head_b)

if not entrance_a and not entrance_b:
return self.get_node_helper1(head_a, head_b)

if entrance_a and entrance_b:
if entrance_a == entrance_b:
return self.get_node_helper1(head_a, head_b, entrance_a, entrance_b)

return self.get_node_helper2(entrance_a, entrance_b)
else:
return None

例题 LeetCode # 160

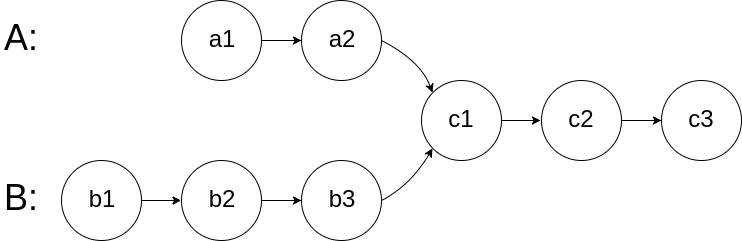
编写一个程序,找到两个单链表相交的起始节点。

如下面的两个链表:

在节点 c1 开始相交。

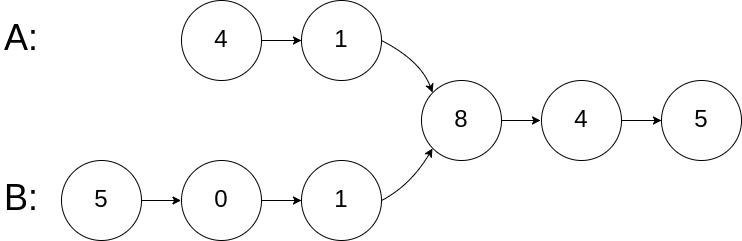
示例 1:

1
2
3
输入:intersectVal = 8, listA = [4,1,8,4,5], listB = [5,0,1,8,4,5], skipA = 2, skipB = 3
输出:Reference of the node with value = 8
输入解释:相交节点的值为 8 (注意,如果两个列表相交则不能为 0)。从各自的表头开始算起,链表 A 为 [4,1,8,4,5],链表 B 为 [5,0,1,8,4,5]。在 A 中,相交节点前有 2 个节点;在 B 中,相交节点前有 3 个节点。

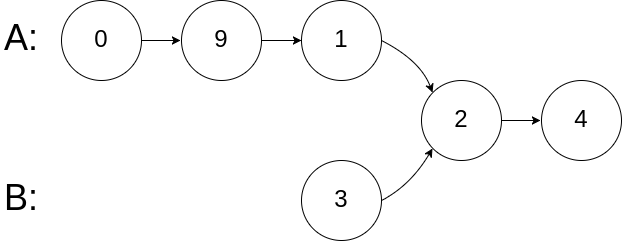
示例 2:

1
2
3
输入:intersectVal = 2, listA = [0,9,1,2,4], listB = [3,2,4], skipA = 3, skipB = 1
输出:Reference of the node with value = 2
输入解释:相交节点的值为 2 (注意,如果两个列表相交则不能为 0)。从各自的表头开始算起,链表 A 为 [0,9,1,2,4],链表 B 为 [3,2,4]。在 A 中,相交节点前有 3 个节点;在 B 中,相交节点前有 1 个节点。
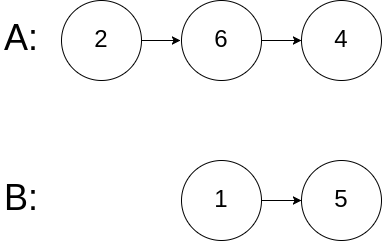
示例 3:

1
2
3
4
输入:intersectVal = 0, listA = [2,6,4], listB = [1,5], skipA = 3, skipB = 2
输出:null
输入解释:从各自的表头开始算起,链表 A 为 [2,6,4],链表 B 为 [1,5]。由于这两个链表不相交,所以 intersectVal 必须为 0,而 skipA 和 skipB 可以是任意值。
解释:这两个链表不相交,因此返回 null。

注意:

  • 如果两个链表没有交点,返回 null.
  • 在返回结果后,两个链表仍须保持原有的结构。
  • 可假定整个链表结构中没有循环。
  • 程序尽量满足 O(n) 时间复杂度,且仅用 O(1) 内存。

Java

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
32
33
34
35
36
37
38
39
40
41
42
43
44
45
46
47
class ListNode {
int val;
ListNode next;

ListNode(int x) {
val = x;
}
}

public class IntersectionList {
public ListNode getIntersectionNode(ListNode headA, ListNode headB) {
ListNode tmpA = headA;
ListNode tmpB = headB;
int count = 0;

while (tmpA != null) {
count++;
tmpA = tmpA.next;
}

while (tmpB != null) {
count--;
tmpB = tmpB.next;
}

if (tmpA != tmpB)
return null;

// 无论 A 和 B 谁长都能保证 tmpA 始终指向长的, tmpB 指向短的
tmpA = count > 0 ? headA : headB;
tmpB = tmpA == headA ? headB : headA;
count = count > 0 ? count : -count;

// 将长的链表指针拨到与另一条链表等长处
while (count != 0) {
count--;
tmpA = tmpA.next;
}

while (tmpA != tmpB) {
tmpA = tmpA.next;
tmpB = tmpB.next;
}

return tmpA;
}
}

Python

1
2
3
4
5
6
7
8
9
10
11
12
13
14
15
16
17
18
19
20
21
22
23
24
25
26
27
28
29
30
31
class ListNode:
def __init__(self, x):
self.val = x
self.next = None

class IntersectionList:
def get_length(self, head):
count = 0
while head:
count += 1
head = head.next

return count, head

def getIntersectionNode(self, head_a, head_b):
length_a, tail_a = self.get_length(head_a)
length_b, tail_b = self.get_length(head_b)

tmp_a = head_a if length_a > length_b else head_b
tmp_b = head_b if tmp_a == head_a else head_a
steps = abs(length_a - length_b)

while steps != 0:
steps -= 1
tmp_a = tmp_a.next

while tmp_a != tmp_b:
tmp_a = tmp_a.next
tmp_b = tmp_b.next

return tmp_a